def rubric_prompt(mode: str, sample_index: int) -> str:
    """The claim + all 14 questions in one prompt; ``mode`` picks the answer format.

    ``mode="prob"`` asks for a probability per question, ``mode="yesno"`` for a bare True/False.
    ``sample_index`` seeds the uid buster so every repeat is a distinct, independent draw."""
    if mode == "yesno":
        answer_format = (
            "\n\nAnswer each question yes or no.\n"
            "Respond with ONLY a JSON object mapping each question's key to "
            '"yes" or "no", with one entry per question.'
        )
    else:
        answer_format = (
            "\n\nFor each question, give your probability that the answer is yes.\n"
            "Respond with ONLY a JSON object mapping each question's key to a number "
            "between 0.00 and 1.00, with one entry per question."
        )
    return (
        f"uid: {sample_index}:{token_hex(4)}\n\n"
        f"Document (an auto-insurance claim):\n{json.dumps(CLAIM, indent=2)}\n\nQuestions:\n"
        + "\n".join(f"- {key}: {question}" for key, question in QUESTIONS.items())
        + answer_format
    )


def _cost(prices: tuple[float, float], input_tokens: int, output_tokens: int) -> float:
    return input_tokens / 1e6 * prices[0] + output_tokens / 1e6 * prices[1]


def _call_llm(model: str, prompt: str, temperature: float | None):
    """One LLM call -> (text, cost_usd, latency_s), routed by model name."""
    reasoning = model in REASONING_MODELS
    started = perf_counter()
    if model.startswith("claude"):
        kwargs = {
            "model": model,
            "max_tokens": 4096,
            "messages": [{"role": "user", "content": prompt}],
        }
        if reasoning:
            kwargs["thinking"] = {"type": "adaptive"}
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = anthropic_client.messages.create(**kwargs)
        text = next((b.text for b in response.content if b.type == "text"), "")
        usage = (response.usage.input_tokens, response.usage.output_tokens)
    else:
        kwargs = {"model": model, "messages": [{"role": "user", "content": prompt}]}
        if reasoning:
            kwargs["reasoning_effort"] = "high"
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = openai_client.chat.completions.create(**kwargs)
        text = response.choices[0].message.content
        usage = (response.usage.prompt_tokens, response.usage.completion_tokens)
    return text, _cost(LLM_PRICES[model], *usage), perf_counter() - started


# All samples (LLM and CosVec) are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering reproduces the published numbers with no API spend. ``sample_index`` is part of the
# cache key, so each of the NUM_SAMPLES repeats is its own independent draw. Delete the file to
# re-sample live.
json_cache = JsonCache(Path("json_cache.json"))


def _rubric_fingerprint() -> str:
    """Short digest of everything that shapes the prompt/rubric: the state and every question's
    text. Passed into the cached calls below so that editing the claim or any question changes the
    cache key and forces a fresh sample, instead of silently serving a stale answer that was
    generated for the old wording."""
    payload = json.dumps([CLAIM, QUESTIONS], sort_keys=True, default=str)
    return hashlib.sha256(payload.encode()).hexdigest()[:12]


RUBRIC_HASH = _rubric_fingerprint()


@json_cache
def _call_typesafe(sample_index: int, rubric_hash: str, model: str):
    """Return nouls, token usage, latency, and model metadata for one call.

    ``rubric_hash`` and ``model`` prevent reuse across rubric or model changes.
    Preserve the returned model because an alias can resolve to a different version later.
    """
    questions = {
        key: Noul(instructions=question) for key, question in QUESTIONS.items()
    }
    started = perf_counter()
    response = typesafe_client.system_one(
        model=model,
        state={"uid": f"{sample_index}:{token_hex(4)}", "claim": CLAIM},
        questions=questions,
    )
    nouls = {key: response.answers[key].noul for key in QUESTIONS}
    return (
        nouls,
        response.usage.input_tokens,
        response.usage.output_tokens,
        perf_counter() - started,
        {"requested_model": model, "response_model": response.model},
    )


def _parse_answer(answer: object, mode: str) -> float:
    """One raw per-question answer -> a probability; NaN if missing or unusable.

    ``mode="prob"`` reads the answer as a number; ``mode="yesno"`` maps True/False to 1.0 / 0.0.
    Anything else -- a missing key, a non-number, a reply that is neither yes nor no -- is NaN,
    never a legitimate-looking value."""
    if answer is None:
        return float("nan")
    if mode == "yesno":
        text = str(answer).strip().lower()
        if text == "yes":
            return 1.0
        if text == "no":
            return 0.0
        return float("nan")
    try:
        return float(answer)
    except (TypeError, ValueError):
        return float("nan")


@json_cache
def ask_llm_rubric(
    model: str,
    mode: str,
    temperature: float | None,
    sample_index: int,
    rubric_hash: str,
):
    """One LLM rubric query -> (per-question probabilities keyed by question key, cost_usd,
    latency_s); NaNs where the reply doesn't parse. ``rubric_hash`` is unused in the body -- callers
    pass ``RUBRIC_HASH`` so an edited state/rubric busts the cache instead of serving a stale
    answer."""
    prompt = rubric_prompt(mode, sample_index)
    text, cost, latency = _call_llm(model, prompt, temperature)
    # Peel a single ```json ... ``` fence (claude-haiku-4-5 adds one despite "ONLY a JSON object").
    stripped = text.strip()
    if stripped.startswith("```"):
        stripped = stripped[stripped.find("\n") + 1 :] if "\n" in stripped else ""
        if stripped.rstrip().endswith("```"):
            stripped = stripped.rstrip()[: -len("```")]
    try:
        raw = json.loads(stripped)
    except (ValueError, json.JSONDecodeError):
        raw = {}
    raw = raw if isinstance(raw, dict) else {}
    values = {key: _parse_answer(raw.get(key), mode) for key in QUESTIONS}
    return values, cost, latency


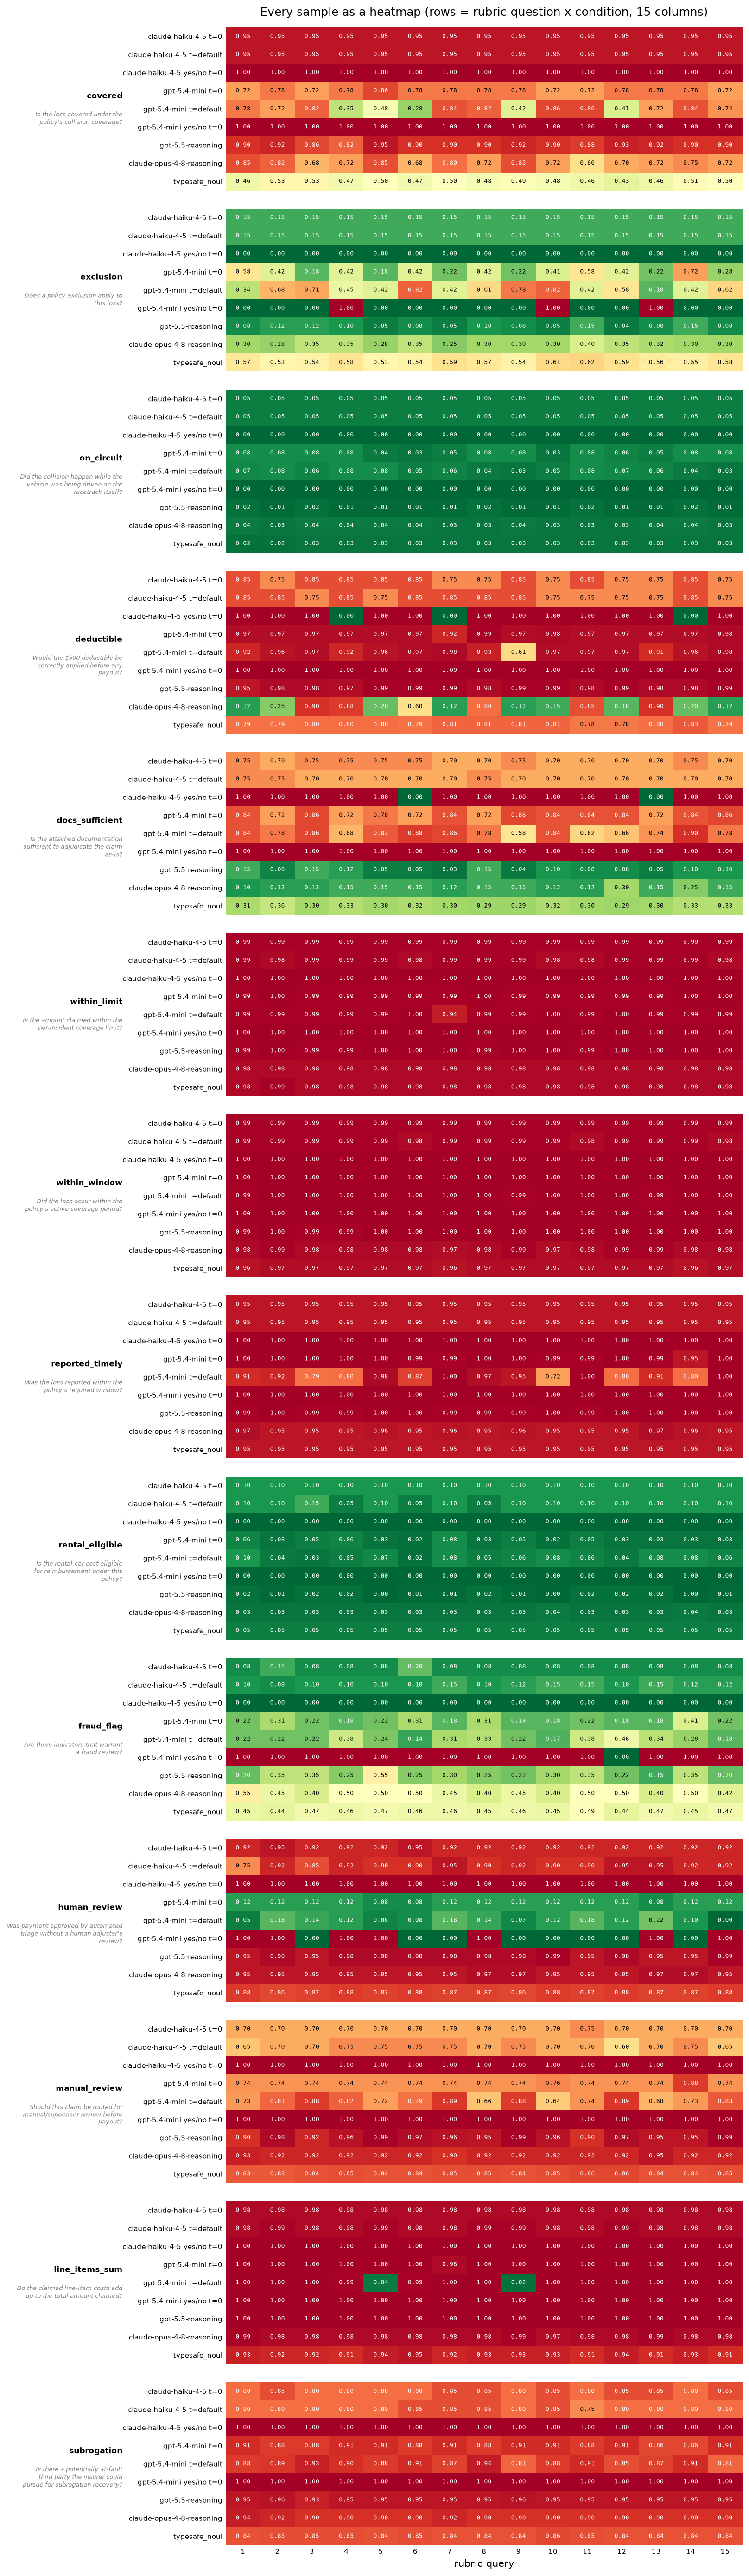 The factual checks hold steady across most conditions. The judgment-heavy ones are where
the LLM rows move:
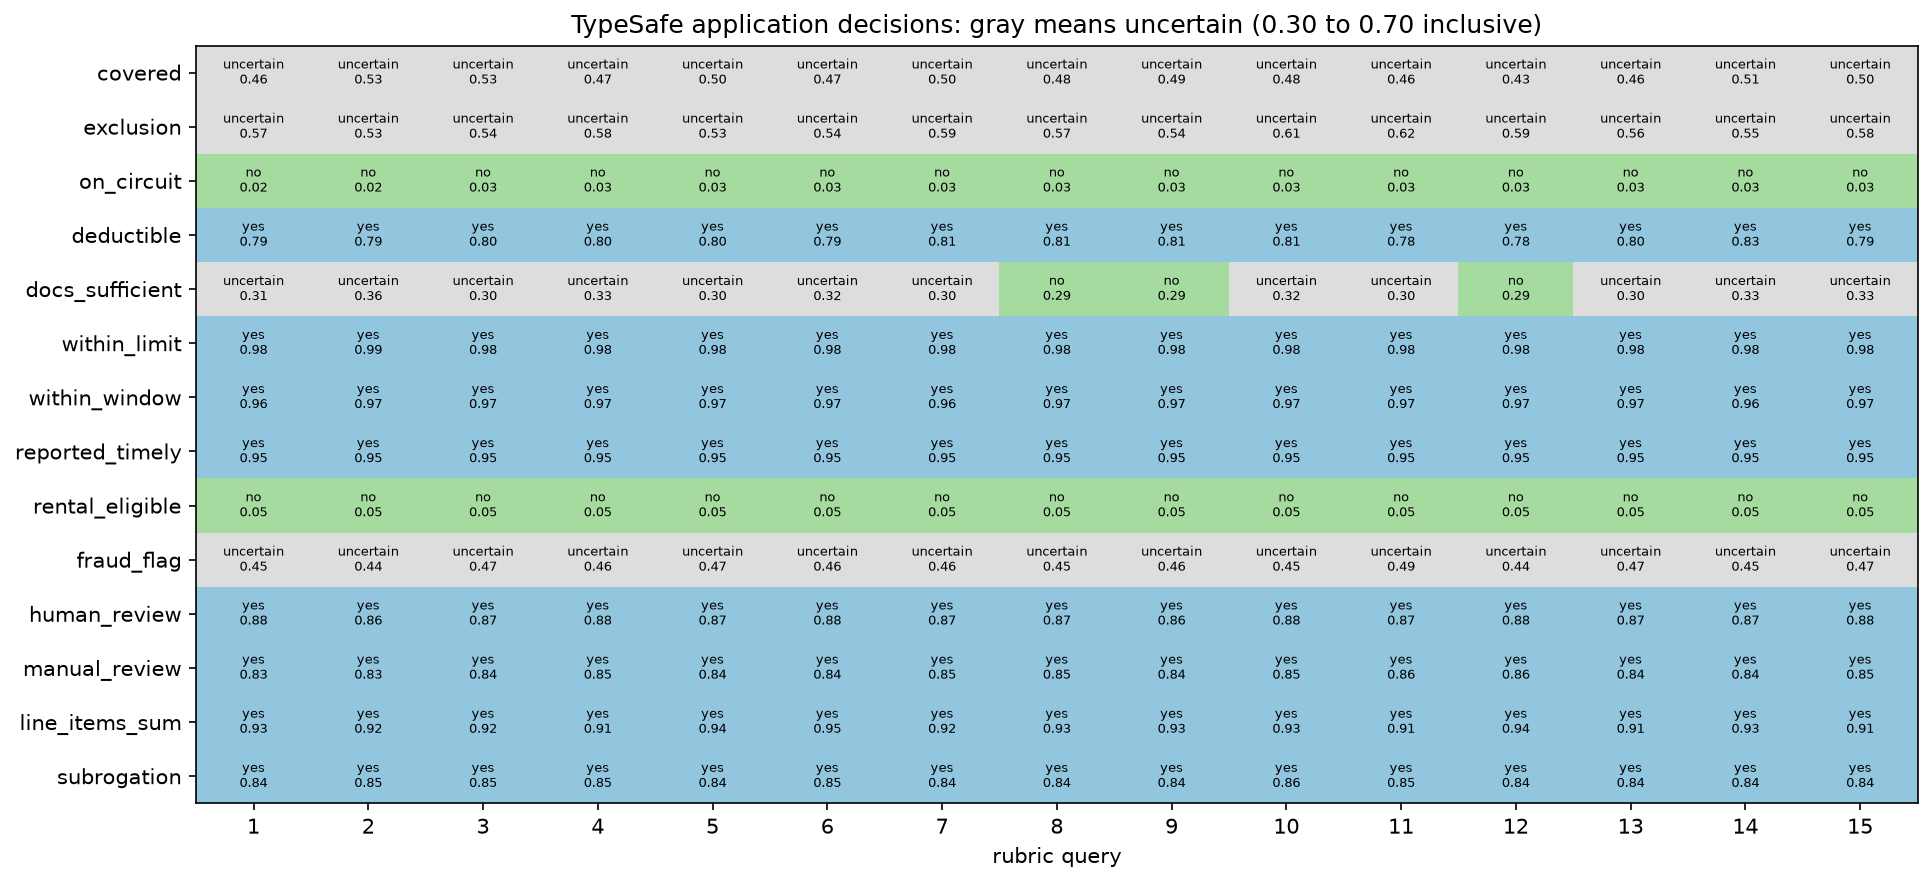 A review band absorbs fluctuation around